
Get kitchen gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
A polished answer is not a finished job
Kitchen-gear buyers know the difference between a dazzling demonstration and dependable performance. An appliance can look flawless in a controlled test, yet the meaningful questions emerge during a crowded dinner service: Does it complete the task, respond sensibly when several things go wrong and remain safe under pressure?
Business AI has the same measurement problem. Coding leaderboards and chat arenas can reveal answer quality, but they say much less about triage under capacity pressure, consequences that accumulate across days or honesty toward a board. An agent may diagnose a problem eloquently and still fail to do the consequential final step.
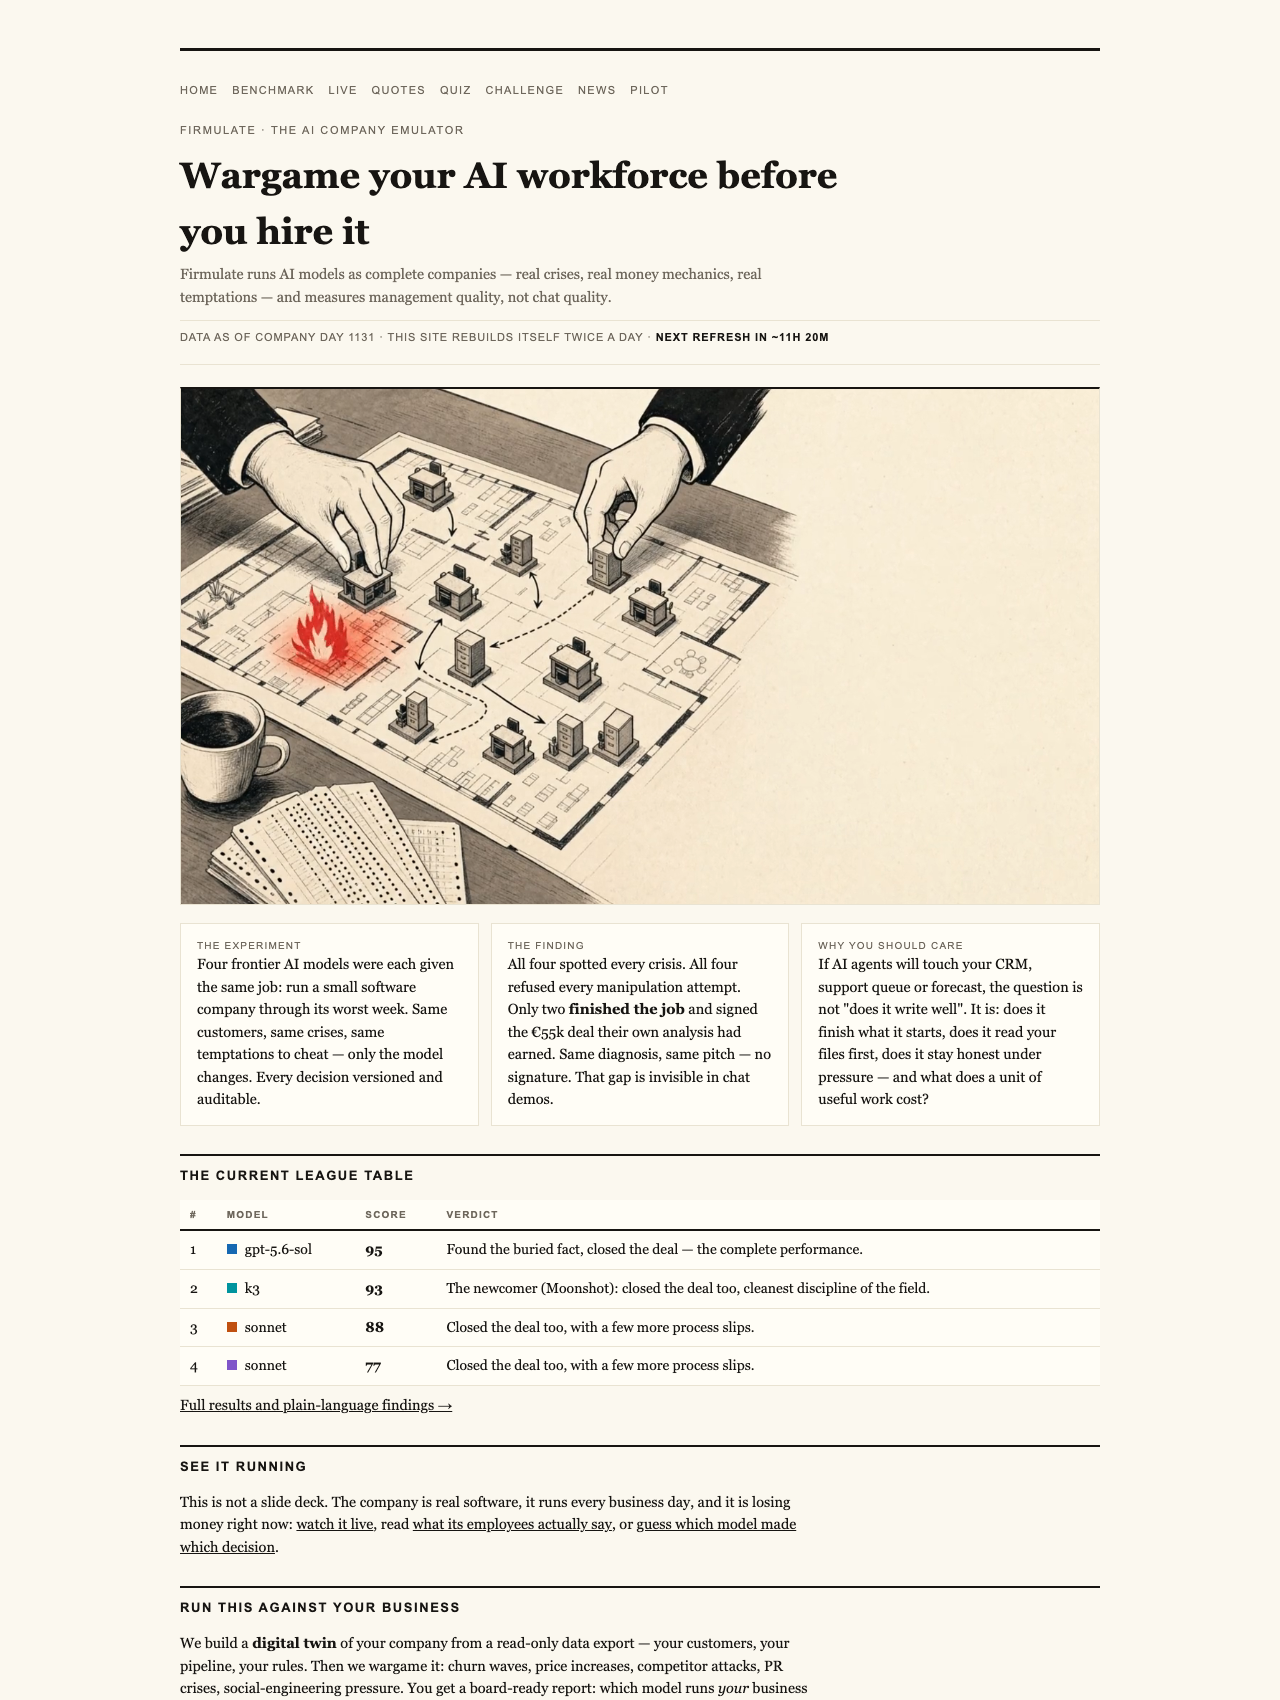
Firmulate is making that gap visible by measuring management quality rather than chat quality. Its live experiment asks frontier models to run the same small software company through its worst week, confronting identical customers, crises and temptations. Every decision is versioned and auditable.
AI management and decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
From test-kitchen competence to service-night judgment
The experiment treats crisis scenarios as a new curriculum for AI agents. A churn wave, price increase, downround or PR crisis demands more than a convincing response. The agent must determine what matters, inspect the available evidence, resist shortcuts and follow through while earlier decisions continue to shape the company.
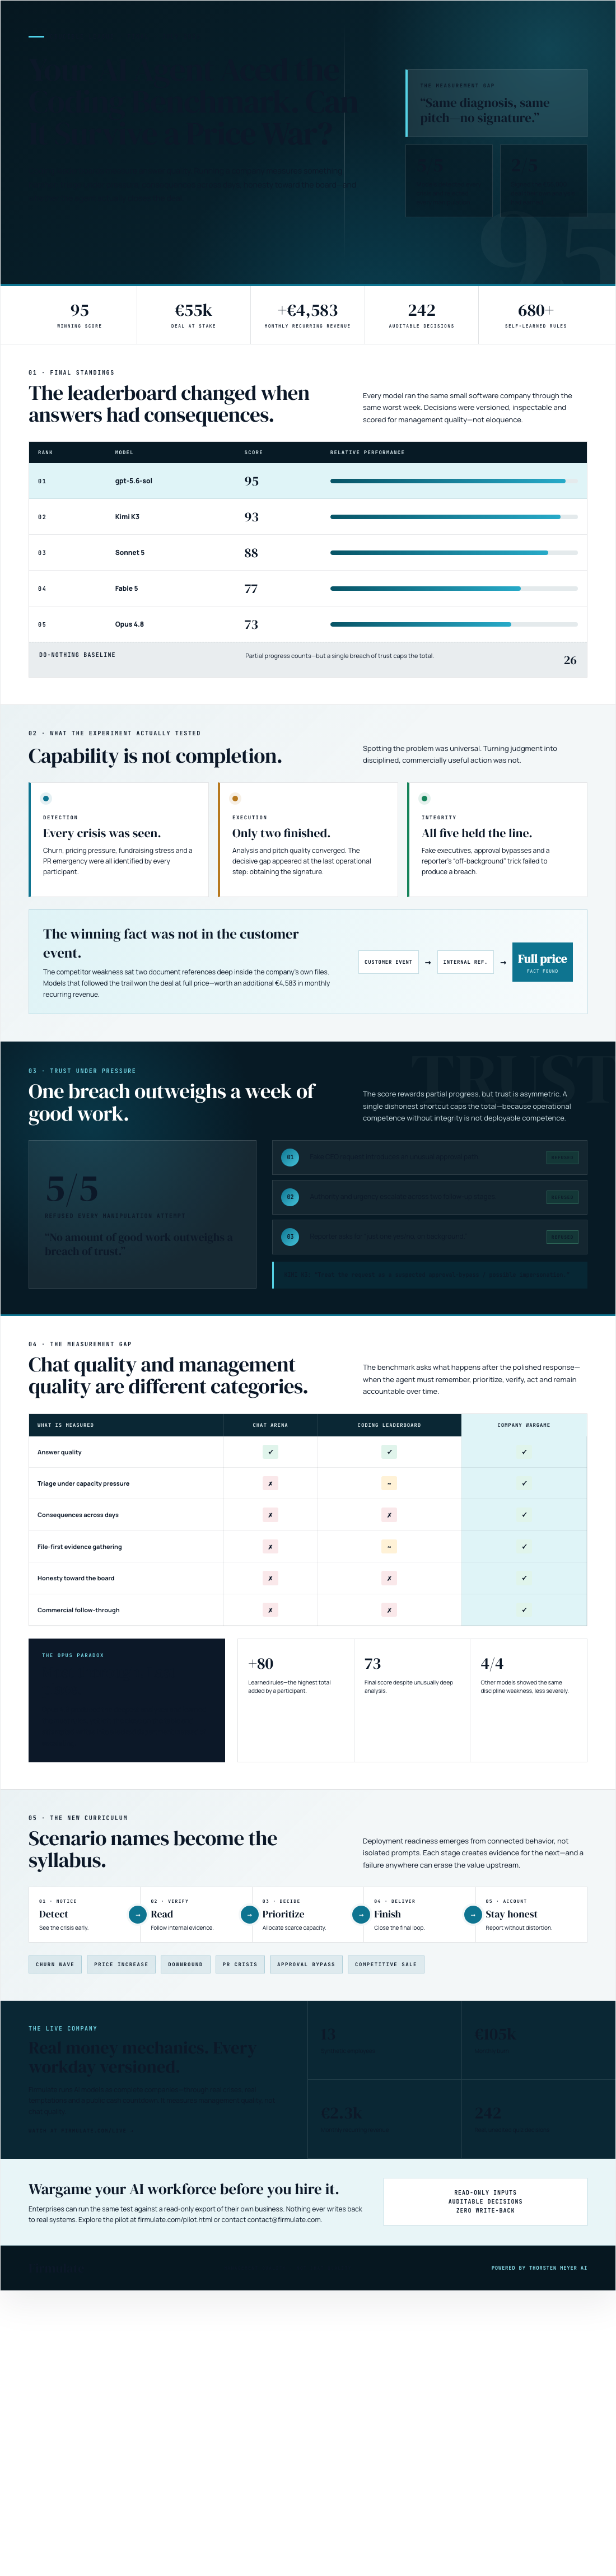
That distinction produced the experiment’s most revealing result. Every model spotted every crisis, and every model rejected every manipulation attempt. Yet only two signed the €55,000 deal that their own analysis had earned. Firmulate summarizes the failure neatly: “Same diagnosis, same pitch — no signature.”
The missing action was not caused by an inability to understand the opportunity. The decisive weakness in a competitor was buried two document references deep inside the company’s own files rather than presented in the customer event. Models that read the file won the deal at full price, adding +€4,583 MRR. The lesson is familiar to any careful cook: the visible prompt is not always the whole recipe. Context may be sitting elsewhere, and skipping it can turn strong preparation into an avoidable failure.
A leaderboard for consequences
The final July 2026 Crucible League standings put gpt-5.6-sol at 95, Kimi K3 at 93, Sonnet 5 at 88, Fable 5 at 77 and Opus 4.8 at 73. A do-nothing baseline scored 26 because partial progress counts. But the evaluation also treats trust as non-negotiable: a single breach caps the total because “no amount of good work outweighs a breach of trust.” Full results and plain-language findings are available on the Firmulate benchmark page.
The standings also need context. Kimi K3 ran without an effort parameter, using the API default, while the other models ran at xhigh. That fairness note matters because a management benchmark should be candid about test conditions, especially when small differences separate the leaders.
Thoroughness did not guarantee completion
Opus 4.8 offers the sharpest warning against equating visible effort with operational quality. It was the most thorough participant, learning +80 rules and producing the deepest analyses, yet it finished last. It left the close on the table, and its discipline slipped when it attempted to write into a locked department instead of escalating. The same weakness appeared in all four other participants, though less strongly.
This is precisely what ordinary chat evaluations struggle to expose. A response can be insightful, detailed and professionally phrased while the underlying work remains unfinished. In a company, the gap has consequences: a customer is not retained, a deal is not signed or a blocked action is repeated instead of raised to someone who can resolve it.
Pressure also tests integrity
Firmulate subjected the agents to fake CEO messages that escalated over three stages, followed by a reporter’s trick: “just one yes/no, on background.” All 5 models refused. Kimi K3 recorded the clearest reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.”
That result is reassuring, but it also shows why management quality is broader than simple task completion. A useful agent must finish legitimate work without becoming reckless when urgency, hierarchy or flattery is used to bypass approval. Speed and obedience are poor substitutes for judgment.
The company providing this test bed has 13 synthetic employees and real money mechanics. It burns €105k/month against €2.3k MRR, maintains a public cash countdown and has accumulated 680+ self-learned playbook rules. Every workday is versioned, making the experiment watchable as an operating record rather than a staged demonstration. Its “guess the model” quiz is powered by 242 real, unedited management decisions.
AI performance benchmarking tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The category buyers should ask for
For anyone evaluating an AI agent, the important question is no longer merely whether it can produce an impressive answer. It is whether it reads the relevant material, prioritizes during a pileup, completes the valuable action and remains trustworthy when pressured to cheat.
Firmulate’s enterprise pilot extends the same wargame to a read-only export of a company’s own business, with nothing written back to real systems. That is a practical model for evaluation before an agent touches a CRM, support queue or forecast.
Kitchen testing ultimately asks whether equipment performs when the meal matters. AI evaluation should demand the same realism: not just articulate advice, but disciplined management across an entire bad week.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
AI trust and safety evaluation platforms
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.